
How to Use AI Well: A Practical Guide From Beginner to Pro
Four levels of AI skill — from asking your first question to running agents — with the habits, prompt patterns and guardrails that separate people who get real work done from people who get plausible nonsense.
Most people who say “AI doesn’t work for me” are using it the way they used a search box in 2010: a short question, one shot, take whatever comes back. Most people who say it changed how they work did one thing differently — they learned to give the model what it needs, check what it returns, and build small repeatable routines around it. Neither group is smarter than the other. One of them has a method.
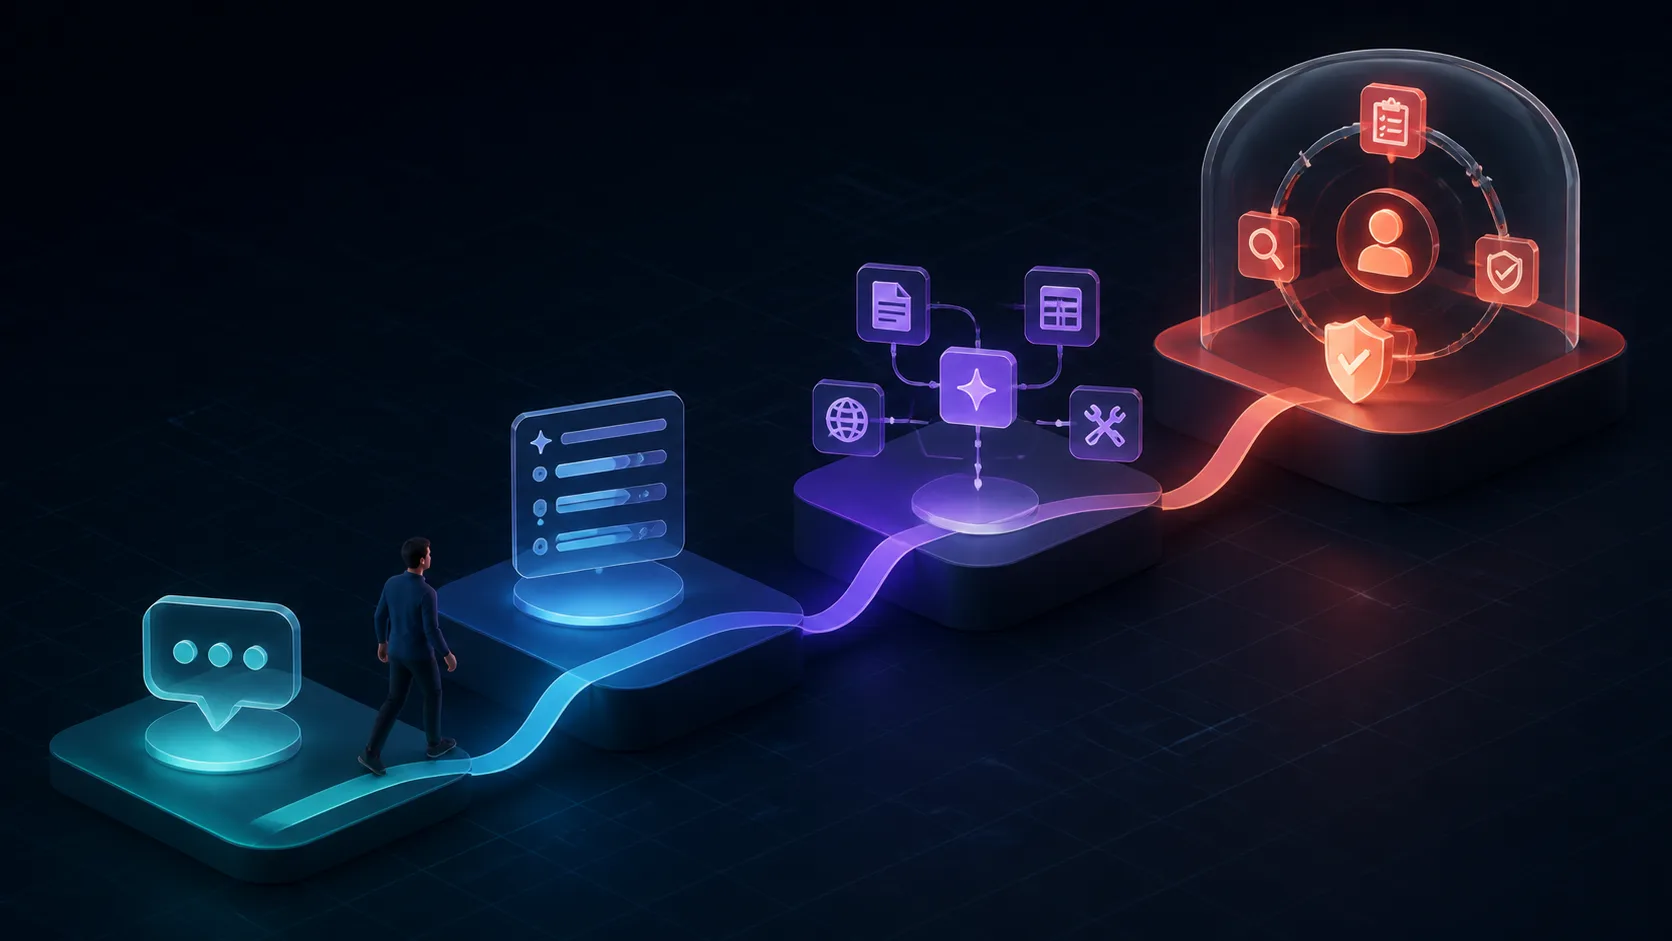
This guide is that method, laid out as four levels. Each level has a mindset, a handful of habits and a concrete example. You do not need to finish one level before touching the next, but skipping the early habits is the most common reason the later ones fail. Hover, tap or focus each step in the diagram to see what defines it.
- Level 1 — Beginner
- Ask and chatYou treat AI as a knowledgeable conversation partner: explain, summarise, draft, brainstorm. The core habits are being specific and reading the answer critically.
- Level 2 — Intermediate
- Context and iterationYou supply role, task, context, format and examples, then refine over several turns. Prompts get reused; outputs get checked against sources.
- Level 3 — Advanced
- Workflows and toolsYou break real work into steps, connect the model to documents, code, spreadsheets and the web, and keep a library of prompts and templates you trust.
- Level 4 — Pro
- Agents and systemsYou design multi-step or multi-agent systems with clear goals, tool access, evaluation and human checkpoints — and you measure whether they actually help.
Why bother climbing? Because the cost of a usable answer falls at every step. A beginner typically needs several attempts and a fair amount of cleanup to get something they can use; someone with a good brief and a workflow gets there in one or two, and spends their time checking rather than rewriting.
- Attempts to a usable answer
- Minutes fixing the output
Show the 8 numbers behind this chart
| Level | Attempts to a usable answer | Minutes fixing the output |
|---|---|---|
| Beginner | 4 | 15 |
| Intermediate | 2.5 | 8 |
| Advanced | 1.5 | 5 |
| Pro | 1.2 | 3 |
Level 1 — Beginner: ask better questions
At this level the tool is a chat window and the goal is simple: get useful answers more often than not. Almost all of the improvement comes from being specific about what you want and honest about what you already know.
- Say what it is for. “Explain compound interest” gets a textbook paragraph. “Explain compound interest to a 16-year-old who is choosing between two savings accounts” gets something usable.
- Give it your material. Paste the email, the paragraph, the error message, the recipe. The model can only work with what is in front of it; it cannot see your screen or read your mind.
- Ask for the shape you need. A list, a table, three options, one paragraph, a subject line under eight words. If you do not say, you get a default.
- Treat the first answer as a draft. Reply with “shorter”, “more formal”, “you missed X”, “try again without the jargon”. The second answer is usually the one you keep.
- Check anything you would be embarrassed to get wrong. Dates, numbers, quotes, names, legal or medical claims and links all need a second source. Models are fluent even when they are wrong.
Good starter uses: summarising long documents, explaining unfamiliar topics at the depth you choose, drafting routine messages, brainstorming lists you then prune, and translating or rewording. Uses to avoid at this level: anything where you cannot judge whether the answer is right.
Level 2 — Intermediate: give context and iterate
The jump from beginner to intermediate is the jump from asking questions to briefing a colleague. A good brief has the same five parts every time. Hover or tap each one below.
- Role
- Sets the lensA role tells the model which expertise and tone to reach for. “You are a senior editor at a business magazine” changes vocabulary, rigour and what it flags.
- Task
- One verb, one objectRewrite this. Compare these. Extract every date. Plan a week. Vague tasks (“help me with this”) produce vague answers.
- Context
- The part most people skipWho it is for, what constraints exist, what you already tried, and the actual material. This is where you close the gaps the model would otherwise fill with guesses.
- Format
- Shape the answerLength, structure, tone and language. Asking for a table or a fixed schema also makes the output easier to check.
- Examples
- The strongest leverOne or two samples of a good result do more than a paragraph of instructions. Show the model the style, the level of detail and the edge cases.
- Better output
- Fewer retriesYou will still iterate — but from a good first draft instead of a generic one.
The other intermediate habit is iterating on purpose. Instead of accepting or rejecting an answer wholesale, steer it: “keep the structure, change the tone”, “the second point is wrong because…”, “give me three alternatives for the opening line”. Long conversations drift, so when the thread gets messy, start a fresh one and paste in only what still matters.
- Ask the model to ask you. “Before answering, ask me up to five questions that would change your answer.” It surfaces the assumptions it was about to make.
- Ask for reasoning when the stakes are high. “Show the steps” or “explain how you got there” makes errors visible; “rate your confidence and say what would change your mind” makes uncertainty visible.
- Use it as a critic, not just a writer. Paste your own draft and ask for the three weakest points. It is often better at critique than at first drafts.
- Save the prompts that worked. A notes file with ten good prompts is worth more than any prompt-engineering course.
Level 3 — Advanced: build workflows and connect tools
Advanced users stop thinking in prompts and start thinking in workflows. A real task — a report, a feature, a research question — is rarely one request. It is a sequence: gather, structure, draft, check, polish. Advanced use means deciding which steps the model does, which steps you do, and what passes between them.
- 1. Gather
- You + AICollect the sources and material: documents, data, previous work, constraints. Ask the model to summarise or extract, but you decide what goes in.
- 2. Structure
- AI proposes, you approveAsk for an outline or plan first. Fix it before anything is written — it is far cheaper to correct a plan than a finished draft.
- 3. Draft
- AIGenerate section by section against the approved plan, feeding in the gathered material. Small pieces are easier to steer and to check.
- 4. Check
- AI + youA second pass: list every factual claim and what supports it, run the tests, compare against the sources. Failures go back to Draft, not to Publish.
- 5. Polish
- YouVoice, judgement and accountability are yours. This is also where you save what worked as a template for next time.
- Decompose first. Ask for an outline or a plan, approve or fix it, then execute section by section. One giant prompt produces one giant, average answer; a plan plus steps produces something you actually control.
- Feed it real sources. Upload the PDF, connect the spreadsheet, point it at the documentation or turn on web search. Grounded answers are checkable answers; ask it to quote the passage it relied on.
- Use the right surface. Chat is for thinking; a document or code editor with AI is for producing; a spreadsheet function or an API is for repeating the same operation a thousand times. Match the tool to the job.
- Write reusable templates. A “meeting notes → action items” prompt, a “review this pull request” prompt, a “turn this brief into a client email” prompt. Fill in the blanks, keep the structure. Most tools let you save these as custom instructions, projects or skills.
- Build a checking step into the workflow. A second pass with “find every factual claim in this and list what needs a source” catches what a single generation misses. For code, that step is running the tests.
For anyone who writes code, this is also the level where AI coding assistants earn their keep: describe the change, let the assistant read the codebase, review the diff, run the tests. The discipline is identical to prose — small steps, real context, verify before you accept.
Level 4 — Pro: agents, systems and measurement
At the top of the ladder you are no longer prompting a model; you are designing a system that uses one. An agent is a model given a goal, a set of tools (files, browser, code execution, APIs) and permission to take several steps on its own. Used well, agents handle whole tasks: triage a support inbox, research a topic across sources, refactor a module, prepare a weekly report. Used carelessly they do the wrong thing quickly and at scale.
- Goal + boundaries
- Written firstWhat does “done” look like, and what may the agent never do without you: send, spend, delete, publish. Constraints are the design, not an afterthought.
- The agent loop
- Plan → act → observeThe model reads the goal, picks a next step, uses a tool, looks at the result and repeats. Good agents show their plan before they act on it.
- Narrow tools
- Least accessRead the ticket queue and draft replies beats full inbox credentials. Every tool you do not grant is a class of mistake that cannot happen.
- Human checkpoint
- Where it mattersPlans, irreversible actions and anything a customer sees get reviewed by a person. Everything else runs unattended.
- Outcome
- Measured, not admiredHours saved, error rate, tickets closed. If the number does not move, the system is a hobby.
- Logs + eval set
- How you improve itEvery step inspectable afterwards, and 20–50 real cases with known-good answers to run every change against. What they teach goes back into the goal.
- Write the goal and the boundaries first. What does “done” look like? What may it never do (send emails, spend money, delete files) without a human? Constraints are the design, not an afterthought.
- Give narrow tools rather than broad access. An agent that can read the ticket queue and draft replies is safer and more useful than one with your full inbox credentials.
- Put humans at the checkpoints that matter. Plans, irreversible actions and anything customer-facing get reviewed. Everything else can run.
- Evaluate, don’t vibe-check. Keep a set of 20–50 real examples with known-good answers and run every prompt or system change against them. If you cannot say whether the new version is better, you are guessing.
- Log everything. Every step, tool call and output should be inspectable afterwards. An agent you cannot audit is an agent you cannot trust — or improve.
- Measure the outcome, not the activity. Hours saved, error rate, time-to-first-draft, tickets closed. If the number does not move, the fancy system is a hobby.
Pros also know when not to use AI: for tasks where the checking costs more than the doing, for decisions that need accountability a model cannot carry, and for anything where a confident wrong answer is worse than no answer at all.
One more way to see the climb: at each level, the share of your time that goes into each part of the work shifts. Beginners spend most of their minutes reacting to whatever came back. Pros spend most of theirs on the two things a model cannot do for them — deciding what to ask and checking what they got.
- Briefing & planning
- Waiting & reading
- Fixing what came back
- Checking & measuring
Show the 16 numbers behind this chart
| Level | Briefing & planning | Waiting & reading | Fixing what came back | Checking & measuring |
|---|---|---|---|---|
| Beginner | 10% | 25% | 50% | 15% |
| Intermediate | 25% | 25% | 30% | 20% |
| Advanced | 30% | 20% | 20% | 30% |
| Pro | 30% | 15% | 10% | 45% |
Try it: build a better prompt
The widget below assembles the five-part brief from Level 2. Fill in the fields, watch the prompt take shape, and copy it into whichever assistant you use. Notice how much more specific it is than the one-line question you would normally type.
Habits that apply at every level
- Verify before you rely. The more consequential the output, the more independent the check. Fluency is not accuracy.
- Never paste what you would not email to a stranger. Passwords, client data, unreleased financials and personal details stay out unless your organisation has approved the tool for them.
- Own the output. If you send it, ship it or publish it, it is yours — including the mistakes. “The AI wrote it” is not a defence anyone accepts.
- Prefer clarity over cleverness. Plain, specific instructions beat elaborate ‘magic’ prompts. If a prompt only works with a strange incantation, it will break next month.
- Keep learning by doing. Models change every few months. The habits above do not, but what the model can do well does — re-test your assumptions regularly.
Common mistakes, by level
- Beginner — one-line questions with no context, then blaming the tool for a generic answer.
- Beginner — trusting citations, statistics and quotes without checking them.
- Intermediate — long, drifting conversations where the model has lost track of what was decided ten messages ago.
- Intermediate — writing instructions when an example would have worked better.
- Advanced — one enormous prompt instead of a decomposed workflow, and no checking step at the end.
- Advanced — automating a task before you have done it manually with the model a few times and know what good looks like.
- Pro — giving an agent broad access and vague goals, then being surprised at what it did.
- Pro — shipping prompt changes with no evaluation set, so nobody knows whether things got better or worse.
The 30-day calendar: one thing a day, from Beginner to Pro
Reading about levels does not move you up them; practice does. Below is a calendar of thirty small exercises — one a day, ten to twenty minutes each, colour-coded by the level it trains. Hover, tap or focus a day to see the task. Days 1–7 build beginner habits, 8–15 the five-part brief, 16–23 workflows and tools, 24–30 agents and measurement. Miss a day? Just do it the next one — the order matters more than the dates.
- Day 1 — Pick your tool
- BeginnerChoose one AI assistant and use it for one real task today — an email, a summary, an explanation. Notice what you would normally have done instead.
- Day 2 — Say what it's for
- BeginnerEvery request today gets a purpose: who it is for and what you will do with the answer. Compare against a bare question.
- Day 3 — Paste the material
- BeginnerBring your own material: the email, the paragraph, the error message. Do not make the model guess what you are looking at.
- Day 4 — Ask for a shape
- BeginnerSpecify the format on every request: a list, a table, three options, 100 words. Notice how much less editing you do.
- Day 5 — Iterate once
- BeginnerNever accept the first answer. Reply with 'shorter', 'more formal', 'you missed X' or 'three alternatives' — and keep the second.
- Day 6 — Fact-check day
- BeginnerTake three claims the model gave you this week — a date, a number, a name — and verify each against a real source.
- Day 7 — Week 1 review
- BeginnerWrite down three requests that worked and one that did not, and why. This is the seed of your prompt library.
- Day 8 — Add a role
- IntermediateStart every prompt with 'You are a …' that matches the job: editor, tutor, hiring manager, engineer. Notice the change in tone and rigour.
- Day 9 — One verb, one object
- IntermediateRewrite three vague prompts ('help me with this') into one clear task each: rewrite, compare, extract, plan.
- Day 10 — Write the context
- IntermediateFor one real task, write a full context block: audience, constraints, what you already tried, the source material.
- Day 11 — Format and limits
- IntermediateSet length, structure, tone and language explicitly. Try asking for a table or a fixed schema and see how much easier it is to check.
- Day 12 — Give an example
- IntermediateAttach one sample of what 'good' looks like to a request. Compare with the same request without it.
- Day 13 — Ask it to ask you
- IntermediateAdd 'Before answering, ask me up to five questions that would change your answer.' Answer them, then compare the result.
- Day 14 — Use it as a critic
- IntermediatePaste your own draft and ask for the three weakest points and one alternative structure. Fix, do not just accept.
- Day 15 — Start the library
- IntermediateSave five prompts that worked into a notes file or your tool's saved instructions. Give each a name and a one-line 'when to use'.
- Day 16 — Decompose
- AdvancedTake a real task and ask for a plan first. Approve or fix the plan, then execute it step by step instead of in one prompt.
- Day 17 — Feed a document
- AdvancedUpload a real PDF, spreadsheet or page and work from it. Ask the model to quote the passage each answer relies on.
- Day 18 — Ground it
- AdvancedTurn on web search or connect a source. Ask for sources with every claim and check two of them.
- Day 19 — Build a template
- AdvancedTurn one recurring task into a fill-in-the-blanks prompt: meeting notes → actions, brief → email, PR → review.
- Day 20 — Add a check step
- AdvancedAdd a second pass to your template: 'find every factual claim above and list what needs a source' — or for code, run the tests.
- Day 21 — Pick the surface
- AdvancedDo the same task in chat, in a document or code editor with AI, and (if you can) via a spreadsheet function or API. Note which fits.
- Day 22 — Run it end to end
- AdvancedRun your full workflow — gather, structure, draft, check, polish — on a real deliverable, and time it.
- Day 23 — Week 3 review
- AdvancedCompare the time and quality against doing it by hand. Keep what saved time; drop what did not.
- Day 24 — Define the task
- ProWrite one bounded agent task: what 'done' looks like and what it may never do without you (send, spend, delete).
- Day 25 — Narrow the tools
- ProList the minimum access the agent needs — read the queue, draft replies — and give it nothing more.
- Day 26 — Set checkpoints
- ProDecide where a human reviews: plans, irreversible actions, anything customer-facing. Everything else runs.
- Day 27 — Build an eval set
- ProCollect 20 real examples with known-good answers. This is how you will know whether a change helped.
- Day 28 — Run and log
- ProRun the agent under your review, then read every step of the log. Note where it guessed and where it asked.
- Day 29 — Measure the outcome
- ProScore the run against your eval set and one real metric: hours saved, errors, tickets closed. Adjust the instructions.
- Day 30 — Retrospective
- ProWrite your own one-page guide: the prompts, templates and rules you now trust. Decide what becomes a habit — and repeat the calendar in a month.
The same plan, week by week
- Week 1 — Use AI daily for small real tasks: emails, summaries, explanations. Practise adding purpose, material and format to every request. Check every fact you would repeat.
- Week 2 — Write every prompt with the five-part brief. Start a notes file of prompts that worked. Practise steering: shorter, more formal, missed X, three alternatives.
- Week 3 — Pick one recurring task and turn it into a three-to-five-step workflow with a checking step. Feed it real documents. Save it as a template.
- Week 4 — If your tools allow it, let an assistant or agent run one bounded task end to end under your review. Write down what it may not do, and measure whether it saved time.
Written August 17, 2026. Tools and model capabilities change quickly; the habits here are the part that stays useful.